Open-Vocabulary Video Analytics System: Segmentation, Tracking, & Counting
Author: Ching-Chi Yeung
End-to-end open-vocabulary video analytics combining YOLOE-26 (YOLOE-26l variant) zero-shot segmentation, multi-object tracking, and virtual tripwire line-crossing object counting from text prompts. Supports switchable PyTorch, ONNX GPU FP16, and TensorRT FP16 backends with an interactive tuning UI.
Interface
Interactive control panel for backend selection, open-vocabulary text prompts, confidence thresholding, and tripwire coordinate configuration.
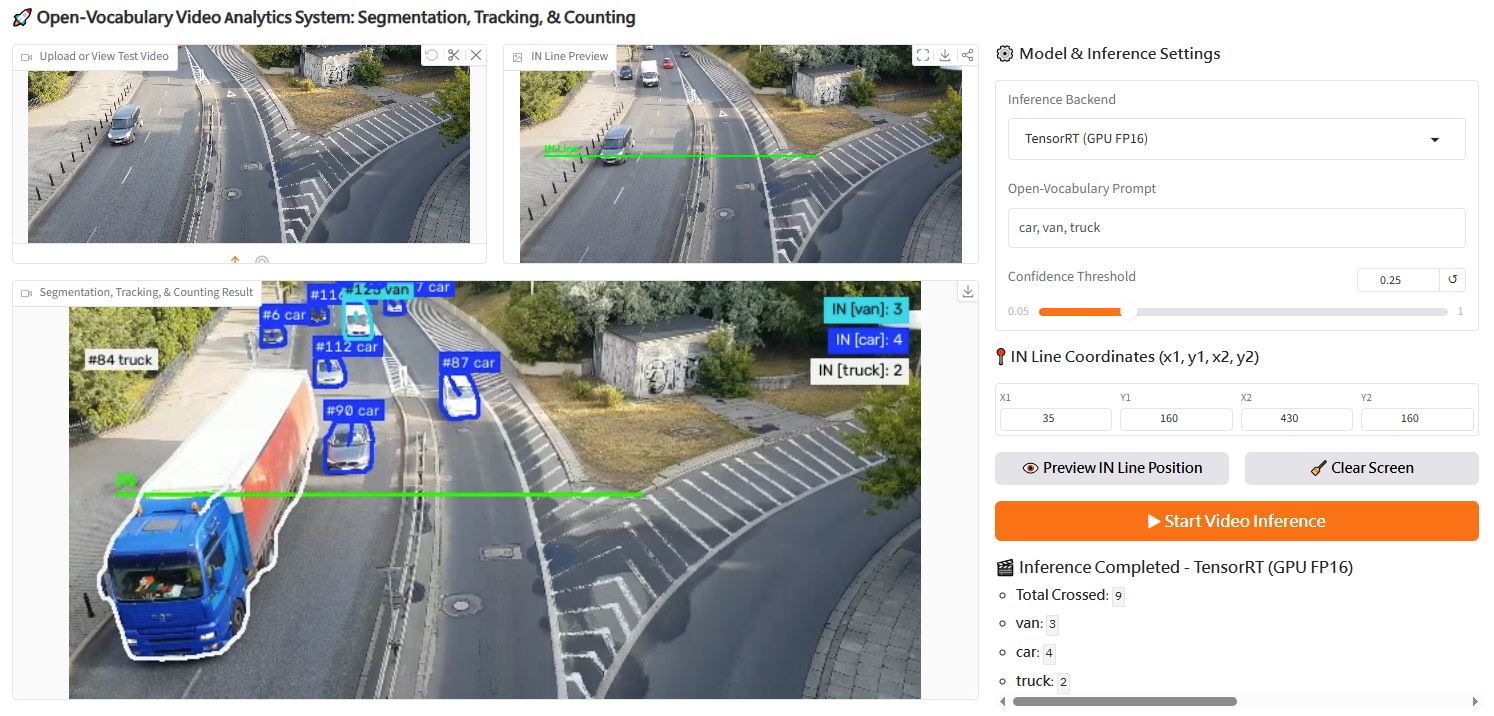
Results
Qualitative comparisons across input video and text-prompted segmentation, tracking, and line-crossing counts.
original
"car, van, truck"
"heavy truck"
"red car"
Performance
Inference latency and throughput benchmark for YOLOE-26l across deployment runtimes (NVIDIA T4 GPU).
| Inference Engine | Precision | Avg. Latency (ms) | Throughput (FPS) | Speedup |
|---|---|---|---|---|
| PyTorch | FP32 | 29.2 | 34.3 | 1.00x (Baseline) |
| ONNX GPU | FP16 | 23.2 | 43.2 | 1.26x |
| TensorRT Optimal | FP16 | 14.3 | 69.8 | 2.04x |
Architecture & Tech Stack
End-to-end video inference pipeline and deployment components.
(Multi-Backend)